AI Voice Agents:
Complete 2026 Guide to How They Work,
What They Do and How to Build One
What AI voice agents are, how they work, what they handle for a business, how they compare with IVR and human agents, where they fall short, and how to build one: pipeline architecture, Vapi vs Retell vs LiveKit, latency, Asterisk and FreeSWITCH integration, cost and a real contact-centre case study, from a team building VoIP systems since 2017.
Kaushik Parmar
Founder & VoIP Architect, CelloIP Technologies
24/7
Calls Answered
~1 s
Target Reply Time
Any
Language
100%
Source Code Yours
Quick answer
What is an AI voice agent, and how do you build one?
An AI voice agent (or voice bot) is software that holds phone conversations on its own. It streams the caller's audio to speech-to-text, sends the transcript to an LLM that decides what to say or which tool to call, and speaks the reply with text-to-speech, ideally within about a second. Add barge-in so callers can interrupt, connect it to phone lines over SIP, and choose a managed platform or a self-hosted stack such as LiveKit or Pipecat.
Contents
What Is an AI Voice Agent?
An AI voice agent is software that answers or makes phone calls and holds a natural spoken conversation on its own. It is also called a voice bot, AI phone agent, AI calling agent or conversational AI agent. The caller speaks normally; the agent understands, looks things up or takes action in your systems, and replies in a natural voice, usually starting about a second after the caller stops speaking.
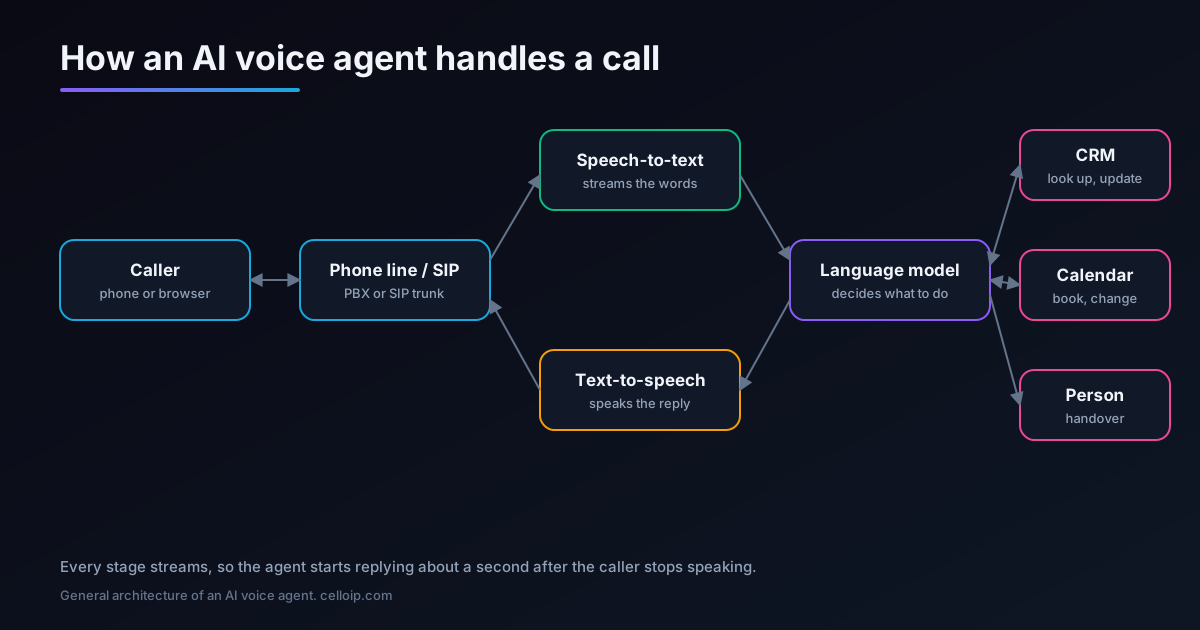
Three things changed between the old phone menus and today's agents: speech recognition became accurate enough for free speech, language models learned to follow instructions and call tools, and synthetic voices became natural. Together they let an agent resolve a request, not just route it.
Modern voice bots have fundamentally replaced the rigid DTMF-based IVR trees that defined phone automation since the 1990s. Instead of "Press 1 for billing, Press 2 for support," a voice bot says "How can I help you today?" — and actually understands the answer, regardless of how the caller phrases it. They handle interruptions, hold context across multi-turn conversations, access live databases via APIs, and escalate to human agents when the situation requires it.
Natural Language
Understands free-form speech, accents, and colloquial phrasing — not just predefined phrases or keywords.
Context Awareness
Maintains conversation history across multiple turns. Remembers what the caller said 3 exchanges ago.
Live API Access
Looks up orders, bookings, accounts, and databases in real time to give accurate, personalised answers.
Barge-In Support
Stops mid-response when the caller interrupts — just like a human would, no awkward robotic pauses.
Human Escalation
Detects frustration, complex queries, or explicit requests and warm-transfers to a live agent seamlessly.
24/7 Operation
Handles thousands of simultaneous calls at any hour without staffing costs or quality degradation.
What AI Voice Agents Handle for a Business
“AI voice agent” and “voice bot” describe the same thing: software that answers or makes phone calls and holds a natural conversation. What has changed since the IVR era is that modern agents understand free speech, keep context across a call and can act in your systems, so they resolve requests instead of only routing them.
The jobs they do fall into two groups. Inbound agents answer calls you receive; outbound agents place calls on your behalf. Outbound brings extra rules on consent and calling hours, so most businesses start inbound.
| Job | Direction | What the agent does | Systems it needs |
|---|---|---|---|
| Receptionist and call answering | Inbound | Greets, answers common questions, routes or takes messages | Knowledge base, PBX transfer |
| Appointment booking | Inbound / outbound | Checks availability, books, reschedules, sends confirmations | Calendar or booking system |
| Order and account status | Inbound | Authenticates the caller and reads back status | Order system, CRM |
| IVR replacement | Inbound | Understands the request and routes or resolves it | PBX or contact centre queues |
| Lead qualification | Inbound / outbound | Asks qualifying questions, scores and logs the lead | CRM |
| Reminders and renewals | Outbound | Calls to confirm, remind or renew, with answering-machine detection | Dialer, consent and do-not-call lists |
| Collections | Outbound | Explains the balance, takes a promise or payment, escalates disputes | Billing, payment gateway |
| Surveys and feedback | Outbound | Runs short spoken surveys and records answers | Survey store, CRM |
For the front-desk case in detail, see our AI receptionist guide. For outbound rules, see TCPA and AI outbound calling and answering machine detection.
AI Voice Agent vs IVR vs Human Agent
An AI voice agent sits between a traditional phone menu (IVR) and a person. It is far more capable than a menu, but it doesn't replace people for complex or sensitive calls. Most businesses use all three together.
| Touch-tone IVR | AI voice agent | Human agent | |
|---|---|---|---|
| How callers interact | Press keys or say set words | Speak naturally | Speak naturally |
| What it can do | Route calls, read fixed information | Answer, look up, book, update, route | Anything, including judgement calls |
| Availability | 24/7 | 24/7 | Business hours, unless staffed around the clock |
| Capacity | Limited by phone lines | Many calls at once, limited by lines and servers | One call per person |
| Cost per call | Lowest | Low: telephony, speech and model usage | Highest: staff time |
| Handles the unexpected | No | Partly; hands over when unsure | Yes |
| Best for | Simple routing | Routine, repeatable calls | Complex, sensitive or high-value calls |
A good set-up lets the AI agent take the routine calls, keeps a simple menu or keypad fallback for callers who prefer it, and passes everything else to people with the context attached. Our guides to replacing an IVR with AI and AI-to-human handover go deeper.
How to Measure Whether an AI Voice Agent Is Working
A demo call proves very little. Agree on a handful of numbers before launch, capture a baseline from your current phone setup, and review them weekly with real call transcripts. These are the metrics we set up on every project.
Resolution (containment) rate
Share of calls the agent completes without a person. Measure per call reason, because a high rate on easy calls can hide failure on important ones.
Transfer rate and reasons
How often it hands over and why: caller asked, low confidence, policy, or failure. Each reason points to a different fix.
Task success
For calls with a goal (book, pay, update), did the goal actually happen in the system? Check the calendar or CRM, not the transcript.
Turn latency
Time from the caller finishing to the agent starting to speak, measured on real calls. Aim for about a second or less.
Caller experience
Short post-call survey, hang-ups during the AI part of the call, and repeat calls within a day for the same issue.
Cost per resolved call
Telephony, speech and model usage plus hosting, divided by calls resolved. Compare with the cost of the same calls handled by staff.
Expect the numbers to improve over the first weeks as transcripts reveal missing knowledge, unclear prompts and awkward call flows. Most gains come from fixing content and flows rather than changing models.
What AI Voice Agents Don't Do Well, and the Risks
AI voice agents are good at routine, well-defined calls. Being honest about their limits is what makes a deployment succeed. Plan for these from the start:
Complex or emotional calls
Complaints, bereavement, disputes and anything needing judgement should go to a person quickly. The agent's job is to recognise these and hand over.
Inventing answers
Language models can state wrong things confidently. Ground answers in your own content, limit actions to defined tools, and make the agent say when it doesn't know.
Noisy lines and accents
Speech recognition struggles with poor lines, heavy background noise and some accents. Confirm names, numbers and dates back to the caller, and test with real recordings.
Names, numbers and spellings
Email addresses, postcodes and unusual names are hard to capture by voice. Spell back, send a text link for complex details, or hand over.
Calling rules
Outbound AI calls are regulated in many countries, including consent and disclosure rules. Check the rules for every country you call before launch.
Data and recordings
Calls contain personal data. Decide where audio and transcripts are stored, who can access them and for how long, and tell callers when calls are recorded.
None of these are reasons to avoid AI voice agents; they are reasons to scope them carefully, start with the calls they handle well, and review transcripts every week. See our guides to testing and monitoring voice agents and outbound calling rules.
Buy an App, Build on a Platform, or Build Custom?
There are three realistic ways to get an AI voice agent. The right one depends on call volume, how deeply it must connect to your systems and phone network, and where call data is allowed to live.
Off-the-shelf app
Best for: Small teams with simple, standard calls
Build on a managed platform
Best for: Validating a use case quickly with your own logic
Custom or self-hosted build
Best for: High volume, deep integration or strict data rules
A common path is to prove the use case on a managed platform, then move to a self-hosted build once volume makes per-minute fees significant or data rules require it. Designing prompts, tools and integrations to be portable from the start makes that move cheap. The rest of this guide covers how the custom path works.
A Real Example: AI Voice Agent for a Contact Centre
CelloIP built an AI voice agent for a contact centre in North America. It shows how the pieces in this guide fit together in production.
| Jobs | Inbound support, outbound calls and appointment booking |
|---|---|
| Languages | English and Spanish |
| Telephony | The contact centre's existing FreeSWITCH platform, connected to LiveKit over SIP |
| Voice AI | LiveKit Agents with hosted speech-to-text, language model and text-to-speech services |
| Integrations | CRM, booking system and helpdesk |
| Handover | Back to human agents in FreeSWITCH queues, with a summary |
| Timeline | First production version in three to six months; live and maintained by CelloIP |
The key decision was to keep FreeSWITCH in charge of the phone system and add the AI as a participant in the call, so the contact centre kept its numbers, queues and reporting.
Read the full case studyVoice Bot Architecture: The STT→LLM→TTS Pipeline
Every production voice bot is built on three core pipeline stages processing audio in real time. Each stage must stream its output to the next — waiting for completion before passing results is the single biggest source of unacceptable latency.
Caller
Speaks naturally over phone
Stage 1 — STT
Deepgram Nova-3 or Whisper
StreamingStage 2 — LLM
Fast hosted or open model
Token streamingStage 3 — TTS
ElevenLabs · Cartesia · 150–250ms
Audio streamingLiveKit Agents (1.x): a complete speech-to-text, LLM and text-to-speech agent in Python
from livekit import agents
from livekit.agents import Agent, AgentSession
from livekit.plugins import deepgram, elevenlabs, openai, silero

class SupportAgent(Agent):
    def __init__(self) -> None:
        super().__init__(
            instructions=(
                "You are a friendly customer service agent for Acme Corp. "
                "Keep replies under two sentences. If you can't help, "
                "offer to transfer the caller to a person."
            )
        )

async def entrypoint(ctx: agents.JobContext):
    await ctx.connect()

    session = AgentSession(
        vad=silero.VAD.load(),                  # detects when the caller speaks
        stt=deepgram.STT(model="nova-3"),       # 1. speech-to-text (streaming)
        llm=openai.LLM(model="gpt-4o-mini"),    # 2. language model
        tts=elevenlabs.TTS(),                   # 3. text-to-speech (streaming)
        allow_interruptions=True,               # caller can barge in
    )

    await session.start(room=ctx.room, agent=SupportAgent())
    await session.generate_reply(
        instructions="Greet the caller and ask how you can help."
    )

if __name__ == "__main__":
    agents.cli.run_app(agents.WorkerOptions(entrypoint_fnc=entrypoint))
STT Comparison: Best Speech-to-Text APIs for Voice Bots
The STT layer is where most latency problems originate. Use batch APIs and your bot will sound robotic with 1–2 second pauses. Always use streaming STT — transcribing audio chunks in real time as the caller speaks.
| Provider | Latency | Accuracy | Cost | Best For |
|---|---|---|---|---|
| Deepgram Nova-3 | 200–300ms | ★★★★★ | $0.0043/min | Production streaming, low latency |
| OpenAI Whisper Large V3 | 400–600ms | ★★★★★ | $0.006/min | Accuracy-critical, multilingual |
| AssemblyAI Universal-2 | 300–450ms | ★★★★☆ | $0.0062/min | Speaker diarization, sentiment |
| Google Speech-to-Text | 250–400ms | ★★★★☆ | $0.004/min | GCP stack, 125+ languages |
| Whisper (self-hosted) | 100–200ms | ★★★★★ | GPU infra only | HIPAA, full data control |
CelloIP recommendation: Deepgram Nova-3 for most English production agents, after testing alternatives in each language you need. It offers the best balance of latency (200–300ms) and accuracy, with native streaming WebSocket API, automatic punctuation, and smart formatting. Use self-hosted Whisper where audio must not leave your infrastructure. Latency and price figures in these tables are approximate list figures at the time of writing; check current vendor pricing.
TTS Comparison: Best Text-to-Speech for Voice Bots
TTS quality defines whether your bot sounds like a human or a robot. The gap between ElevenLabs and older TTS engines is dramatic. Use sentence-level streaming: synthesise and play the first sentence while the LLM is still generating the second.
| Provider | Latency | Voice Quality | Cost | Best For |
|---|---|---|---|---|
| ElevenLabs Turbo v2.5 | 200–350ms | ★★★★★ | $0.18/1K chars | Most human-like, emotional range |
| Cartesia Sonic | 150–250ms | ★★★★☆ | $0.065/1K chars | Lowest latency, consistent tone |
| OpenAI TTS | 250–400ms | ★★★★☆ | $0.015/1K chars | Cost-effective, 6 voices |
| Google Cloud TTS | 200–350ms | ★★★★☆ | $0.004/1K chars | Lowest cost, WaveNet/Studio |
| XTTS (self-hosted) | 80–150ms | ★★★☆☆ | GPU infra only | Custom voice cloning, HIPAA |
VAPI vs Retell AI vs LiveKit vs Bland AI: Platform Comparison 2026
Four platforms dominate the voice AI market in 2026. Where previously you had to stitch together Twilio, a custom WebSocket server, Deepgram, OpenAI, and ElevenLabs from scratch — taking months — you can now launch a working voice bot in hours. But each platform makes different trade-offs between speed, cost, control, and compliance.
VAPI
Best for MVPs & Speed
$0.05–0.10/min
Latency: 400–600ms
Best for: Startups, MVPs, fast launch
LiveKit
Best for Enterprise & HIPAA
Infra cost only
Latency: 300–500ms
Best for: HIPAA, on-premise, scale
Retell AI
Best for Outbound Campaigns
$0.07–0.12/min
Latency: 450–650ms
Best for: Outbound calls, simple IVR replacement
Bland AI
Best for High-Volume Outbound
Custom enterprise
Latency: 400–600ms
Best for: Enterprise high-volume outbound
Full Feature Comparison
| Feature | VAPI | LiveKit | Retell AI | Bland AI | Custom Build |
|---|---|---|---|---|---|
| Open Source | No | Yes ✓ | No | No | Yes ✓ |
| Self-Hostable | No | Yes ✓ | No | Partial | Yes ✓ |
| HIPAA BAA | Enterprise | Self-host ✓ | Enterprise | Enterprise | Yes ✓ |
| Custom LLM | Partial | Any ✓ | No | No | Any ✓ |
| SIP/PSTN | Yes | Yes ✓ | Yes | Yes | Yes |
| Cost/minute | $0.05–0.10 | Infra only ✓ | $0.07–0.12 | Enterprise | Infra only ✓ |
| E2E Latency | 400–600ms | 300–500ms ✓ | 450–650ms | 400–600ms | 300–500ms ✓ |
| Voice Cloning | Limited | Yes (XTTS) | Limited | Yes | Yes ✓ |
| Outbound Dialing | Yes | Yes | Yes ✓ | Yes ✓ | Yes |
| WebSocket API | Yes | Yes ✓ | Yes | Yes | Yes ✓ |
| Time to Launch | Hours | Days | Hours | Weeks | 8–16 weeks |
Latency Optimisation: Achieving Sub-Second Response Time
Long silences make callers think the call has dropped or that the agent didn't understand. Aim for about a second or less from the moment the caller stops speaking to the moment the agent starts replying; well-tuned streaming pipelines often do much better. These techniques get you there:
Stream STT in real-time
Use Deepgram's streaming API. Don't wait for end-of-utterance — start LLM inference as soon as confidence is high enough.
LLM streaming (token-by-token)
Send each LLM token to TTS immediately. Don't wait for the full response. First audio byte should play before LLM finishes.
TTS with sentence-level streaming
Split LLM output at sentence boundaries. Begin synthesising and playing the first sentence before the second is generated.
Co-locate all services
Run STT, LLM inference, TTS, and your bot server in the same AWS/GCP region. Every 100ms of network hop adds to end-to-end latency.
VAD-based turn detection
Use Silero VAD instead of silence timers. Detect end-of-speech in <100ms without misclassifying pauses mid-sentence.
Pre-warm your LLM
Keep a persistent LLM session open. Cold-start GPU memory allocation adds 200–400ms to the first response.
Latency Budget: Sequential vs Streaming
Illustrative figures in milliseconds, not measurements from a specific deployment.
Integrating Voice Bots with Asterisk & FreeSWITCH
For enterprise deployments, voice bots must integrate with your existing telephony infrastructure — typically Asterisk or FreeSWITCH. All major platforms (VAPI, Retell, LiveKit) expose a SIP endpoint. Your PBX routes calls to that SIP URI instead of an agent extension.
Asterisk extensions.conf — Route DID to VAPI voice bot
[from-pstn]
exten => +12025551234,1,NoOp(Route to AI voice bot)
 same => n,Answer()
 same => n,Dial(PJSIP/+12025551234@vapi-bot,60)
 same => n,Hangup()

; PJSIP endpoint — pjsip.conf
[vapi-bot]
type=endpoint
transport=transport-udp
context=from-vapi
disallow=all
allow=ulaw
allow=alaw
aors=vapi-bot-aor

[vapi-bot-aor]
type=aor
contact=sip:sip.vapi.ai:5060
LiveKit SIP dispatch rule (CLI) — Route inbound calls to agent
# 1. Create SIP trunk in LiveKit
lk sip inbound create \
  --name "asterisk-inbound" \
  --numbers "+12025551234"

# 2. Create dispatch rule — route to voice bot room
lk sip dispatch create \
  --rule-type individual \
  --room-prefix "call-" \
  --trunk-id YOUR_TRUNK_ID

# 3. Point Asterisk at LiveKit SIP endpoint
; pjsip.conf
[livekit-sip]
type=endpoint
host=sip.livekit.cloud
port=5060
allow=ulaw,alaw,opus
End-to-End SIP Architecture
AI Voice Agent Use Cases by Industry
Voice bots deliver the highest ROI in high-volume, repetitive phone interactions where callers need immediate answers but the interaction doesn't require true human judgment. These are the most common sectors:
Customer Service
Handle FAQs, order status, returns, account lookups — resolve routine inbound calls without a human agent and hand the rest over with context.
Healthcare
Appointment booking, medication reminders, post-discharge follow-up, triage, designed around healthcare privacy rules on self-hosted infrastructure.
Real Estate
Qualify inbound leads, book showings, follow up with prospects — 24/7 without a sales team answering phones.
Finance / Insurance
Payment reminders, loan status, policy renewals, fraud alerts — automated outbound and inbound at enterprise scale.
SaaS / CPaaS
Embed AI phone calling into your product via LiveKit or VAPI SDK — add a phone number to your platform without telephony expertise.
HR & Recruiting
Screen candidates at scale, schedule interviews, collect references — reaching far more candidates than a team could call by hand.
HIPAA Compliance & Voice Bot Security
Healthcare, finance, and government voice bots have strict compliance requirements. HIPAA bots cannot send PHI to third-party APIs without a BAA. The safest pattern is self-hosted infrastructure where no patient data leaves your environment; your compliance team confirms the final setup.
Voice Bot Stack for HIPAA Requirements
Encrypted SIP signalling and media transport
Audio never sent to Deepgram or OpenAI APIs
On-premise inference — PHI stays on your servers
Voice synthesis on your infrastructure
Call logs and transcripts encrypted with KMS
Every API call, data access, and call event logged
Compliance Checklist
Using Deepgram or ElevenLabs without a BAA for healthcare calls. Even if audio is encrypted in transit, the vendor still processes PHI. Always confirm BAA availability before selecting a provider for healthcare voice bots.
Voice Bot Development Process
A typical plan for a single-use-case agent runs about eight weeks, as below. Agents with several languages, many integrations or several call types take longer; the contact-centre agent in our case study took three to six months.
Discovery & Architecture
Week 1
Define call flows, integration requirements, SIP server audit and model selection.
Pipeline Setup
Week 2
STT + LLM + TTS integrated end-to-end. First working call in a sandbox environment.
SIP / PSTN Integration
Week 3
Asterisk/FreeSWITCH trunk configured. Bot receives and initiates real phone calls.
Business Logic & Flows
Weeks 4–6
All call flows, API integrations (CRM, calendar, database), webhook handlers built.
Latency & Quality Tuning
Week 7
Streaming tuned for sub-second responses. Voice quality reviewed. Interruption handling polished.
QA, Load Test & Launch
Week 8
100-call concurrency test, edge cases, failover tested. Production deployment and monitoring configured.
Voice Bot Development Cost & Pricing
Fixed-price milestone contracts. No hourly billing surprises. Pricing depends on platform choice, number of call flows, integrations, and compliance requirements.
MVP Voice Bot
$8,000–$20,000
4–6 weeks
Best for: Startups, proof of concept
Production Agent
$25,000–$60,000
8–16 weeks
Best for: Growth-stage, enterprise
Enterprise / Regulated
Scoped after discovery
Agreed in the plan
Best for: Healthcare, finance, govt
Hire Voice Bot Developers
CelloIP builds production AI voice agents on your phone system, in any language. Fixed-price or dedicated-team options, an NDA whenever you need one, and full source code handover.
Fixed-Price Project
Defined scope, milestone payments, no surprises. MVP in 4–6 weeks from $8,000.
Get a QuoteDedicated Bot Developer
A full-time senior voice AI engineer embedded in your team. You own the code and IP.
Hire a DeveloperFrequently Asked Questions
What is an AI voice agent?
An AI voice agent is software that answers or makes phone calls and holds a natural conversation on its own. It turns the caller's speech into text, uses a language model and tools to decide what to say or do, and replies with synthesised speech. Voice bot, AI phone agent and AI calling agent are other names for the same thing.
What is a voice bot?
A voice bot (also called an AI phone agent) is a system that conducts natural spoken phone conversations without any human. The caller speaks; the bot transcribes the audio (STT), feeds it to an LLM for understanding and response, converts the reply to speech (TTS), and plays it back — all within 400–600ms. Unlike old IVR trees, voice bots understand free-form speech, handle complex queries, and escalate to humans when needed.
How much does voice bot development cost?
An MVP voice bot on VAPI or Retell AI costs $8,000–$20,000 (4–6 weeks). A custom enterprise voice bot on LiveKit with SIP integration, custom LLM fine-tuning, privacy controls, CRM integrations and an admin dashboard typically costs $25,000–$60,000 (8–16 weeks). Ongoing cost: $0.05–0.12/minute on managed platforms, or $0.01–0.03/minute equivalent on self-hosted LiveKit at scale.
VAPI vs LiveKit — which should I choose?
Choose VAPI if you need to go live in days, want a fully managed service, and your call volume is moderate. Choose LiveKit if you need HIPAA compliance, want to use custom or self-hosted LLMs, need full data sovereignty, or are at scale where per-minute fees significantly impact margins. LiveKit also gives tighter control over SIP integration with Asterisk and FreeSWITCH.
Can I build a HIPAA-compliant voice bot?
Yes. HIPAA-compliant voice bots require: BAA-signed managed platforms or fully self-hosted infrastructure, on-premise LLM inference (Llama 70B-class or Mistral 8x7B), encrypted audio (TLS + SRTP), zero PHI sent to third-party APIs, and complete audit logging. Self-hosted LiveKit with Asterisk is a common architecture for this.
How do you integrate a voice bot with Asterisk?
For VAPI/Retell: configure a PJSIP peer in Asterisk pointing at the platform's SIP endpoint, and add a dialplan extension to route your DID to that peer. For LiveKit: configure LiveKit SIP server, create a SIP trunk from Asterisk to LiveKit's SIP URI, and set up dispatch rules in LiveKit to route calls to your agent worker.
What is the latency target for a production voice bot?
Target under 600ms end-to-end. This is the sum of: STT transcription (200–300ms streaming), LLM first token (150–300ms), and TTS first audio chunk (150–250ms). With streaming at every layer and co-located infrastructure, 400–500ms is achievable. Callers begin to notice unnatural silence at around 700ms.
What LLMs work best for voice bots?
Fast models with reliable tool calling matter more than the largest model. Hosted models from OpenAI, Anthropic and Google all work well; the smaller, faster tiers usually give the best balance of speed and quality on the phone. Where data must stay on your servers, open-weight models such as Llama or Qwen can run on your own GPUs with vLLM. Test candidates on your own call transcripts before choosing.
Can voice bots handle interruptions?
Yes. Production voice bots implement 'barge-in' — when the caller starts speaking mid-response, the bot immediately stops its TTS playback, sends an interruption event to the LLM, and begins listening again. This requires tight WebSocket integration between the media server, VAD, and TTS playback buffer. LiveKit Agents SDK handles this natively.
Ready to build your AI voice bot?
Talk to a Voice AI Engineer